Top Post
Market Opportunity of Data Integrity
November 13, 2026
17 mins read
Demand for verifiable data integrity grows with regulation. See the spend behind it and how zkDatabase proves each operation with Zero-Knowledge Proofs.


TL;DR: Demand for verifiable data integrity is rising, driven by regulation and by systems that need provable data rather than trusted reports. zkDatabase meets this with end-to-end cryptographic proofs across the data lifecycle, letting organizations prove integrity without exposing sensitive data. This positions verifiable data as core infrastructure for compliance-first systems.

zkDatabase turns every record in a database into a self-verifying asset. Regulators, partners, and on-chain programs can check the math instead of trusting the operator. With Zero-Knowledge Proofs and Proof-Carrying Data, the whole dataset becomes verifiable in near real time, with each proof generated in about 0.4 seconds.
The Pain Points of the Market Recently
One of the major challenges in today's decentralized ecosystems is the inability of data consumers to verify the authenticity and integrity of the data they rely on. This vulnerability opens the door to fraud and manipulation directly at the data source, a critical flaw in many supposedly trustless systems.
Data consumers can not verify the authenticity/integrity of the data, which leads to fraud and manipulation at the data source.
Let's take Hyperliquid as an example. In March 2025 a trader used a large JELLYJELLY short to push losses into Hyperliquid's HLP vault. Hyperliquid's validators then voted to delist the JELLY market and settled open positions at $0.0095, a price they set rather than the market price (The Block, "Hyperliquid delists JELLYJELLY memecoin amid whale manipulation fiasco", March 2025). This incident highlighted oracle pricing and insurance mechanism weaknesses despite Hyperliquid's audited smart contracts and HyperBFT consensus.

When nothing proves how a data provider sampled and processed a value, every consumer has to trust that provider, and that trust is where manipulation starts.
-
Data verification is inefficient in a traditional Database Management System (DBMS)The verification process in traditional database management systems (DBMS) incurs costs primarily due to the computational and resource-intensive tasks involved in ensuring data integrity, consistency, and security.These tasks include validating data against predefined constraints, running complex queries for consistency checks, and performing authentication or access control to prevent unauthorized access. This can take hours or days.
-
Lack of security/guarantee in the interoperabilityCross-communication between different systems without Proof-Carrying Data (PCD) is risky because it lacks a mechanism to cryptographically verify the integrity and correctness of data exchanged across systems.Without PCD, systems must trust incoming data, which can be manipulated or corrupted, leading to errors, security breaches, or unauthorized actions.
Why This Market Is Compelling
At Orochi, we see six concentric circles of spend converging on the same pain points, Provable Data Integrity:
- Core cryptography tools: Zero-Knowledge Proofs (ZKPs), Proof-Carrying Data (PCD), Fully Homomorphic Encryption (FHE).
- Data pipelines & databases: the budgets zkDatabase can replace or augment.
- Regulated, trust-craving verticals: finance, critical IoT, identity, and RegTech, where proof requirements are exploding.
- Data bridge for blockchains: Securing cross-chain interoperability with Proof-Carrying Data.
- Replace the need for Oracle: zkDatabase can do better than what Oracle did, with a cryptographically verifiable outcome.
- Unlimited off-chain storage: Allowing a chain system to access an unlimited amount of data securely.
Together, the four spend pools in the table below already add up to about $150B in annual spend (2024 and 2025 baselines) and are compounding faster than the general IT sector.
We believe that the broad adoption of zkDatabase is inevitable
Initially, we see the core limitation of current Web2 databases. Traditional relational or NoSQL systems protect data with access controls, encryption at rest, replication, and audit logs. Those measures secure availability and confidentiality, but they do not produce an independently verifiable guarantee that:
- Every record originated from an authenticated source.
- Every update followed defined rules.
- Every query result reflects the authorised state at the time of the request.
Auditors, partners, and regulators must therefore rely on operator-controlled logs, point-in-time exports, or SOC-style attestations, all of which assume good faith from the database administrator.
- With zkDatabase, organizations move from "asserted integrity" to provable integrity.
- Compliance shifts from periodic document audits to continuous, machine-verifiable proofs, reducing reporting overhead while meeting emerging regulatory mandates in finance, healthcare, IoT, and digital identity.
Our market thesis is clear - Organizations will transition from mainstream Cloud databases to zkDatabase.
Regulatory mandates now require independently verifiable data trails
- MiCA (Regulation (EU) 2023/1114) requires crypto-asset trading platforms to keep order records that supervisors can check, and requires issuers of asset-referenced and e-money tokens to hold reserves that are independently audited.
- EU GMP Annex 1 (sterile drug manufacture) requires continuous, tamper-evident monitoring of environmental and temperature data.
- The EU AI Act (Regulation (EU) 2024/1689) sets data governance, record-keeping and traceability duties for "high-risk" AI systems.
Conventional services (AWS Aurora, Azure Cosmos DB, Google Spanner, MongoDB Atlas, Oracle Autonomous DB) offer encryption and access logs but cannot hand regulators one cryptographic artifact that proves every ingest, update and query complied with policy. zkDatabase is built to supply exactly that artifact.
Regulators may come to treat Zero-Knowledge Proofs and Proof-Carrying Data the way they treat digital signatures and hash functions today. A proof can cover a statement about your data without exposing the data or weakening your controls. The acceptance of ZKPs and PCD will be a boost for zkDatabase's adoption.
Budget is already earmarked for solutions that prove integrity
- Gartner puts the database management system market at $119.7 billion in 2024, up 13.4% that year, and forecasts $161 billion in 2026.
- Published reports put data-pipeline tooling, the layer where proofs are generated and attached, at about $12 to $14 billion in 2025, growing about 20% a year.
- These figures confirm that even a low-single-digit share of new "compliance-ready" deployments represents several billion dollars of annual spend that incumbent databases cannot address.
Proof technology is mature and affordable
The market for Zero-Knowledge Proof as a software and technology is gaining mainstream analyst coverage and is expected to reach about $7.6 billion by 2033 (Grand View Research), driven by lower proof costs and hardware acceleration. Falling unit costs remove the financial barrier to embedding proofs in every transaction.
Also, a single, constant-size proof replaces full data exports and privileged log reviews, cutting external-audit effort from days to seconds. Business partners validate data themselves, eliminating lengthy negotiations over read-only replicas or bespoke APIs.
Because the proof reveals nothing about the underlying records, organisations satisfy audit demands without exposing personal or commercially sensitive data, a requirement that standard log dumps cannot meet.
These lines of spend already come to about $150 billion a year and are all compounding faster than general IT budgets. Hence, regulations now expect cryptographic evidence, budgets are shifting to pay for it, and incumbent Web2 databases cannot deliver it. zkDatabase is built as a drop-in solution that covers the entire data life-cycle with one independently verifiable proof, making replacement both necessary and economically rational.
Hence, these build on our R&D efforts.
- They prove there is now a sizeable, budgeted requirement for verifiable data integrity and audit.
- They expose a gap none of the incumbent platforms fill.
zkDatabase is designed specifically to cover the entire data lifecycle, ingest, transform, store and query, with one constant-size, independently verifiable proof.
That end-to-end guarantee is exactly what the converging budget lines now require, and it is not available from any existing Web2 database or partial-proof alternative.

There are visible quantified demand drivers, and we believe that a single-digit share of these overlapping pools yields a serviceable market >$4B for zkDatabase by the end of the decade.
| Spend pool | Baseline | Outlook | Growth |
|---|---|---|---|
| Data-pipeline tooling | about $12.3 to $13.8 billion (2025, range across published reports) | $43.6 to $52.5 billion (2032) | about 20% to 23% a year |
| Database management systems (DBMS) | $119.7 billion (2024, Gartner) | $161 billion (2026, Gartner forecast) | 13.4% (2024) |
| Zero-knowledge proof software | $1.28 billion (2024, Grand View Research) | $7.59 billion (2033) | 22.1% |
| RegTech | $15.80 billion (2024, Fortune Business Insights) | $82.77 billion (2032) | 22.8% |
- Data-pipeline tooling: Every change-data-capture (CDC) or ETL job that regulators now require to emit a mathematically verifiable proof is an incremental demand for zkDatabase's Verifiable Data Pipeline. The 20%+ CAGR shows budgets are already expanding for modernization; adding proof output is an upsell, not an entirely new cost line.
- DBMS spend. Gartner reports that cloud database platform as a service took most of the 2024 growth. As banks and pharma labs re-platform, they choose between traditional logs plus manual audits and a proof-native database. Even a 5% share of these regulated database deployments is a multibillion-dollar revenue ceiling for zkDatabase.
- ZKP software. This pool counts ZKP software and proof services. zkDatabase is not a framework reseller; it is itself a high-volume proof generator. As proof volume rises, the database captures a headline portion of this fast-growing metered spend.
- RegTech & blockchain identity. Fortune Business Insights expects compliance software to grow from $15.80 billion in 2024 to $82.77 billion by 2032. Regulators are shifting from PDF audits to cryptographic evidence; zkDatabase supplies that evidence for both transactional books-and-records and privacy-preserving ID storage.
These four pools already come to about $150 billion in annual spend and are compounding faster than general IT budgets. Credible sources therefore support a material serviceable market for zkDatabase (well into the billions) even before considering long-tail adoption in unregulated sectors.
Where Demand for Proof Is Growing
- Capital-markets data: After FTX, and with MiCA in force, venues face pressure to show order-book and reserve records that outside parties can check.
- Pharma & critical IoT: EU GMP Annex 1 requires continuous, tamper-evident monitoring data.
- AI & media authenticity: Deepfake risk is funding on-chain attestation pilots.
- Digital identity: Portable KYC proofs need data-layer integrity without exposing PII.
These verticals already channel tens of billions in IT/security spend; even modest penetration feeds a nine-figure revenue line.
Capital on hand is not the main constraint
- Celestia has raised $55 million for its modular data availability network.
- Avail has secured $43 million in Series A funding (after a $27 million seed round) to offer DA services.
- EigenLayer and its EigenDA service have attracted well over $200 million across several rounds.
These sums are significant, but they target a different problem, guaranteeing that large blocks of rollup data remain retrievable. Money alone does not bridge the architectural gap outlined below, and hence we have spent years on R&D.
Our competitive edge lies in:
- Proof-native demos (Pickles, Plonky3, ZK-STARK) are early-stage or single-stack.
- Data-availability chains (Celestia, EigenDA) secure blobs, not mutable structured data such as documents in collections.
- Cloud DBs with audit logs (AWS QLDB, MongoDB Enterprise) provide checksums, not end-to-end Proof-Carrying Data.
zkDatabase's moat a regulator can verify (within milliseconds) that the entire pipeline (sampling → processing → storage → query) followed the agreed spec. Competitors validate only isolated steps.
To be more precise, we differentiate as core design goals diverge
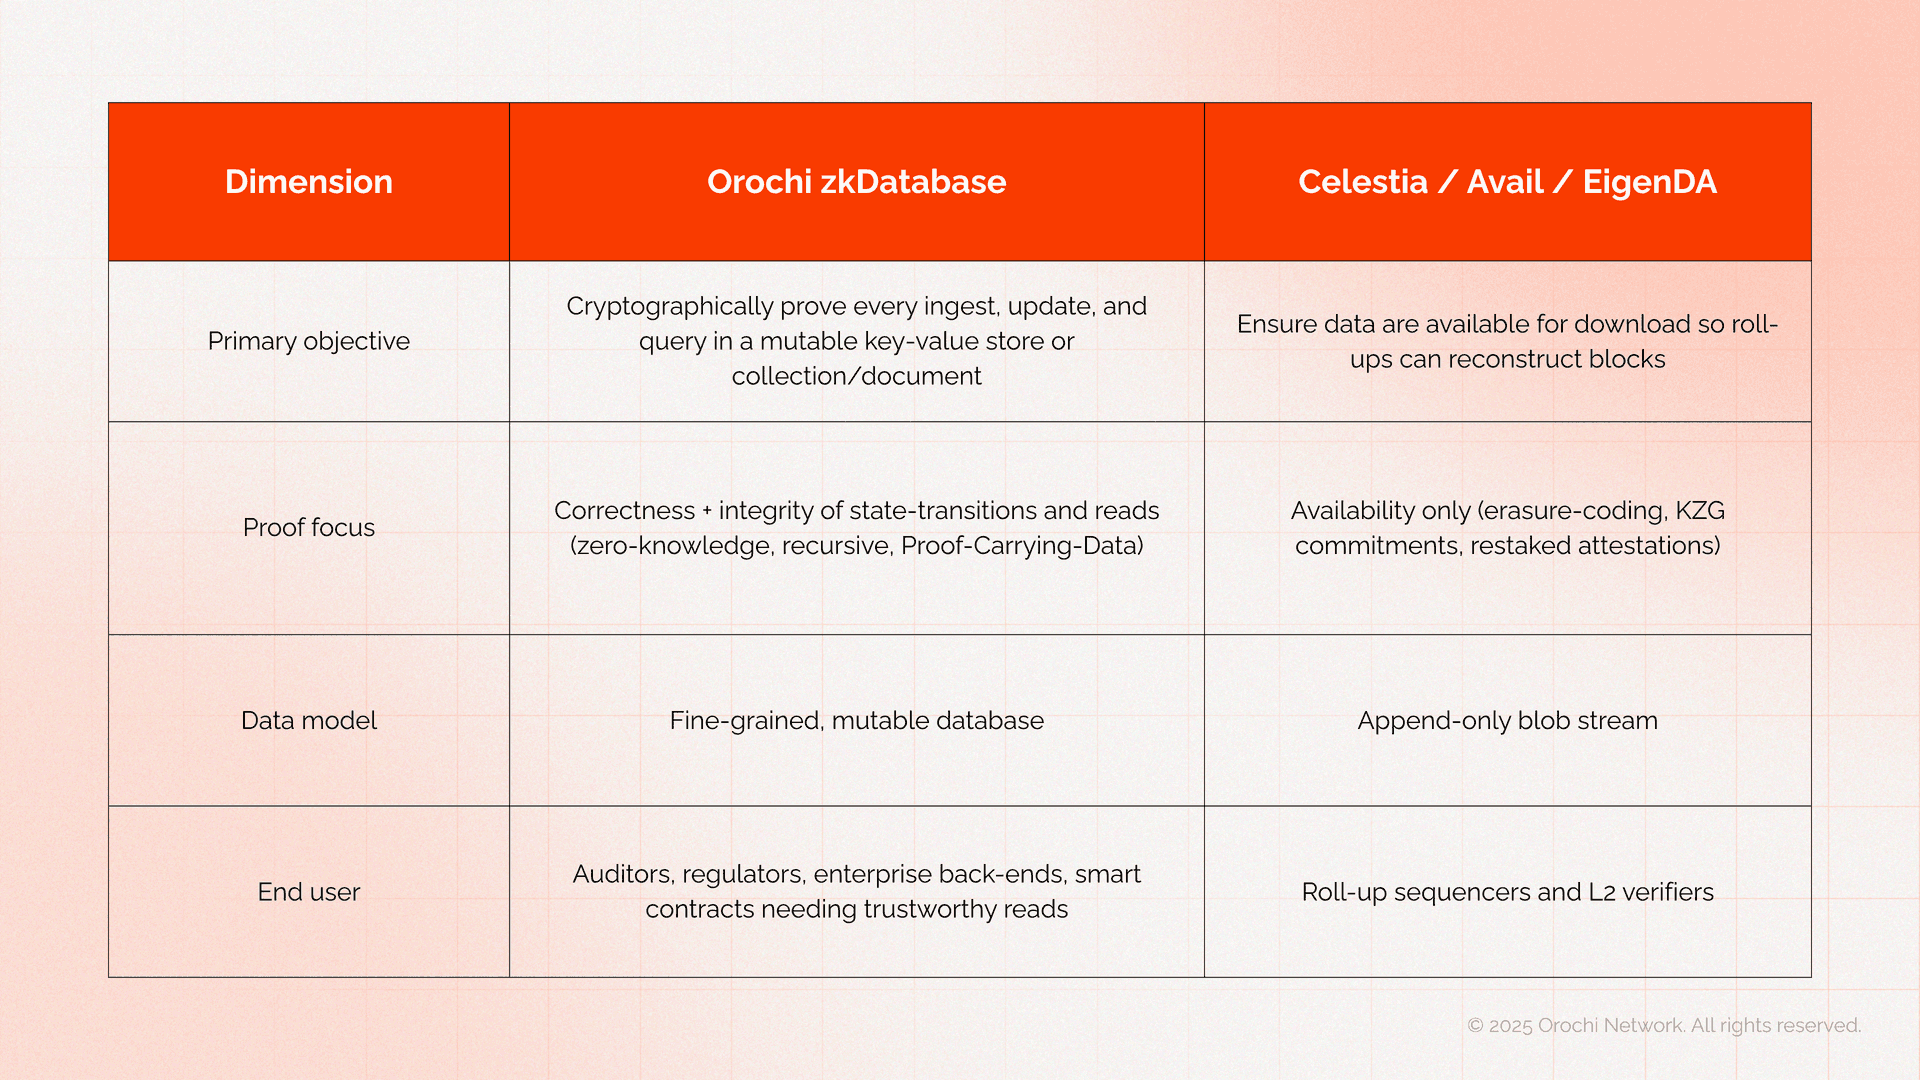
Building a pipeline that certifies state correctness and query accuracy (not merely data presence) requires an entirely separate proof stack (circuits, recursion, Proof-carrying-data composition) that current DA networks do not maintain.
We've spent 5 years on R&D and believe that there are significant technical barriers to replication:
- Recursive proof engineering: zkDatabase runs Groth16 in production, which keeps proofs constant-size (192-byte proofs) and cheap to verify on-chain, at about 100,000 to 150,000 gas. Its proof-system-agnostic design has Plonky3, Halo2, Nova and Pickles planned. DA chains would need to design, audit, and optimise similar circuits for mutable databases; work that typically runs 18-24 months even with a specialised team.
- zkDatabase chains proofs across ingestion, processing, storage, and query. No DA project today exposes APIs or runtimes that accept, compose, and re-emit proofs at each stage. Adding PCD means re-architecting their data path, not a feature toggle.
- DA systems deliver blobs, they do not expose document look-ups, range queries, or JSON transformations. Supporting those operations with integrity proofs demands a new execution layer and client interface.
- Celestia and Avail pay validators to sample and serve data. They have no staking economics that reward the heavy computation needed for zero-knowledge query proofs. Aligning incentives would require contract and token‐design changes.
Hence, we believe that funding alone cannot bridge the architectural, cryptographic, and economic gaps between a data availability layer and a verifiable, mutable database.
- Celestia, Avail, and EigenDA excel at making data retrievable for roll-ups,
- zkDatabase is purpose-built to prove that every piece of enterprise data is authentic and every query is correct. That difference makes direct replication unlikely in the near term.
- And because zkDatabase's proof chain spans the entire data lifecycle, it produces the kind of evidence that new rules in finance (MiCA), life sciences (EU GMP Annex 1) and AI (the EU AI Act) ask for, areas where DA layers are not competing. Replicating that capability is a multi-year effort that would force DA providers to leave their own road maps and re-enter a market Orochi is already addressing.
Here's our take on how we expect Orochi to compete with web2 infra services for mainstream adoption:
We have first matched our business mechanics (revenue engine, cost drivers) and then cross-checked with technology stack motif (the design patterns that determine scalability, security, developer adoption, and compliance posture). Snowflake, MongoDB Atlas, Confluent, Datadog, and Elastic qualify on both criteria:

Because Orochi sits at the intersection of data infrastructure and compliance, the peer set captures the same buyer persona and architectural constraints. DA or execution-only crypto projects address different pain points (throughput, finality) and therefore do not inform enterprise ARR multiples.
Snowflake ↔ zkDatabase & zkDA Layer (roadmap)

- Snowflake demonstrates that enterprises accept relinquishing physical data custody if the platform adds a non-linear benefit (cost/performance).
- Orochi adds a regulatory compliance benefit of similar magnitude, validating its architectural gamble.
MongoDB Atlas & Field-Level Encryption ↔ Proof-Carrying Data

- Atlas adoption of FLE (>1,500 paying customers within 18 months, MongoDB Q4-2024 earnings call) shows that. Client-side augmentation can coexist with managed services. PCD leverages the same trust model but substitutes integrity for confidentiality, so our TAM assumptions mirror Atlas FLE attach rates.
Confluent Kafka Exactly-Once Semantics ↔ Orocle/Orand

- IBM completed its purchase of Confluent in March 2026 at an enterprise value of about $11 billion, a sign of what enterprises pay for reliable real-time data streams.
- Orochi adds a cryptographic guarantee on top of the same kind of data flow.
Datadog Edge Pipelines

- Datadog's market value (about $65 billion in November 2026) rests on agents that run everywhere and enrich data with low latency.
Elastic shard architecture ↔ zkDA Layer

- Elastic's shift from search to observability leveraged its shard retrieval guarantees.
- zkDA, which is on our roadmap and not live yet, is designed to replicate those semantics and add a cryptographic availability proof, lifting reliability from "best-effort" to "provably retrievable", a qualitative upgrade investors can appreciate.
These five data platforms each embody a critical architectural motif that Orochi employs

Because Orochi re-uses these proven motifs, investors can reliably translate technical traction metrics, ingest throughput, proof latency, shard recovery, to financial KPIs already priced into Snowflake, MongoDB, Datadog and Elastic multiples, and into IBM's price for Confluent.
Hence, apart from competing with web3 DA layers, we view Orochi not as "another blockchain infra play" but as the intersection set of five data-platform architectures; each a multi-billion-dollar franchise in its own right.
By exporting Snowflake-grade elasticity, MongoDB-style client augmentation, Kafka-class exactly-once ingestion, Datadog-light edge processing, and Elastic-level retrieval guarantees (then adding cryptographic proofs) Orochi's existing, investable tech motifs into a compliance-first product that existing SaaS benchmarks simply cannot address.
Given that we compete with web2 and web3 services complementarily, we defend our product services as a "one connected, end‑to‑end stack."
We label our products separately (Proof‑Carrying Data (PCD) with zkDatabase, Orocle (oracle), Orand (verifiable randomness), zkDA Layer (on the roadmap, not live yet), and zkVM), yet each component fulfils a specific stage in the same data‑integrity pipeline.

All modules interlock to deliver verifiable data infrastructure, which is Orochi's stated mission. Removing any layer breaks the chain:
- Without Orocle/Orand, there is no trusted entry point for off‑chain facts.
- Without PCD, proofs stop traveling with the data, and downstream systems must trust intermediaries.
- Without zkDatabase, updates become unverifiable, forcing a re‑trust of traditional storage.
- Without zkDA (on the roadmap), data might be proven correct but turn unavailable, blocking audits.
- Without zkVM, computations on the data would need separate verification mechanisms.
Hence, "doing a lot of things" is not diversification for its own sake; it is the required architecture to satisfy regulators and enterprises that need one certificate covering origin, storage, processing, and retrieval. Each Orochi product targets exactly one of those steps, and together they form a closed, verifiable loop.
Our modular approach allows us to develop shared components that can be reused among different products. For instance, Verifiable Data Pipeline and zk-data-rollups can be shared between zkDA, zkDatabase, and Orocle. This approach allowed us to minimize R&D cost and increase the diversity of products to cover a wide range of markets.

Orochi's portfolio is not a scatter of experiments; it is a deliberately layered architecture where every component amplifies the next, culminating in a single cryptographic certificate that regulators and smart contracts can trust. This integrated approach differentiates Orochi from DA‑only or DB‑only providers and positions the project as a comprehensive solution for the emerging verifiable‑data mandate.
Conclusion
Regulators have set immovable deadlines, budgets are migrating from assertion-based controls to cryptographic evidence, and incumbent databases cannot meet the new requirements. zkDatabase is built to:
- Proves every operation (ingest, transform, store, query) with one constant-size certificate.
- Drops into existing stacks without forcing developers to learn new query languages.
- Cut the time to check data from days to seconds while preserving privacy, next to the audits institutions already run.
We estimate a serviceable opportunity above $4 billion by 2030, and we see no direct, full-pipeline competitor today. That is why we expect zkDatabase to become a default data layer wherever provable integrity is required.
Credit: Arhat & Orochi Team
Orochi Network is the Verifiable Data Infrastructure for enterprise systems that ensures data integrity and privacy using advanced cryptography primitives such as ZKP, FHE, and TEE. Its product, zkDatabase, is a verifiable database where every insert, update and query comes with a Zero-Knowledge Proof, so anyone can check it was done correctly while the raw data stays private and off-chain.
FAQs
Question 1: What problem does Orochi's zkDatabase solve that traditional databases can't?
Traditional DBs secure access and encryption but rely on operator-controlled logs for "trust." zkDatabase adds end‑to‑end, cryptographic proofs for ingest, updates, storage, and queries, so auditors and partners can independently verify correctness without seeing raw data.
Question 2: Why is verifiable data integrity an urgent market need now?
New regulations (e.g., MiCA, EU GMP Annex 1, the EU AI Act) increasingly demand independently verifiable data trails. Incumbent cloud databases can't produce a single proof artifact for compliance, while zkDatabase delivers constant‑size proofs that cut audit time from days to seconds.
Q3: How does zkDatabase differ from data‑availability (DA) solutions like Celestia or EigenDA?
DA networks prove data can be retrieved; zkDatabase proves every record is authentic and every query is correct across the full lifecycle. It chains proofs via Proof‑Carrying Data and ZK systems, supporting mutable document workloads, range queries, and compliance‑grade verification in milliseconds.
Talk to Orochi about where proofs fit in your data stack.
Related toTop Post